Blog
We write about RightNow Agent, GPU work, and inference infrastructure.
 LATEST14 min read
LLMs Can Now Write GPU Kernels That Beat torch.compile
We're now seeing multi-agent systems that take your PyTorch code and produce CUDA or Triton kernels with 2x to 14x speedups over torch.compile(mode='max-autotune-no-cudagraphs'). Not on toy benchmarks. On real models like Llama-3.1-8B, Whisper, and Stable Diffusion.
 12 min read
The Complete Guide to Fixing CUDA Installation Issues
Getting CUDA working shouldn't take days. After analyzing hundreds of installation failures, I've compiled every fix you need for PATH errors, driver mismatches, WSL2 problems, and more. Stop fighting with nvcc and start coding.
 8 min read
How to Break the Scaling Wall
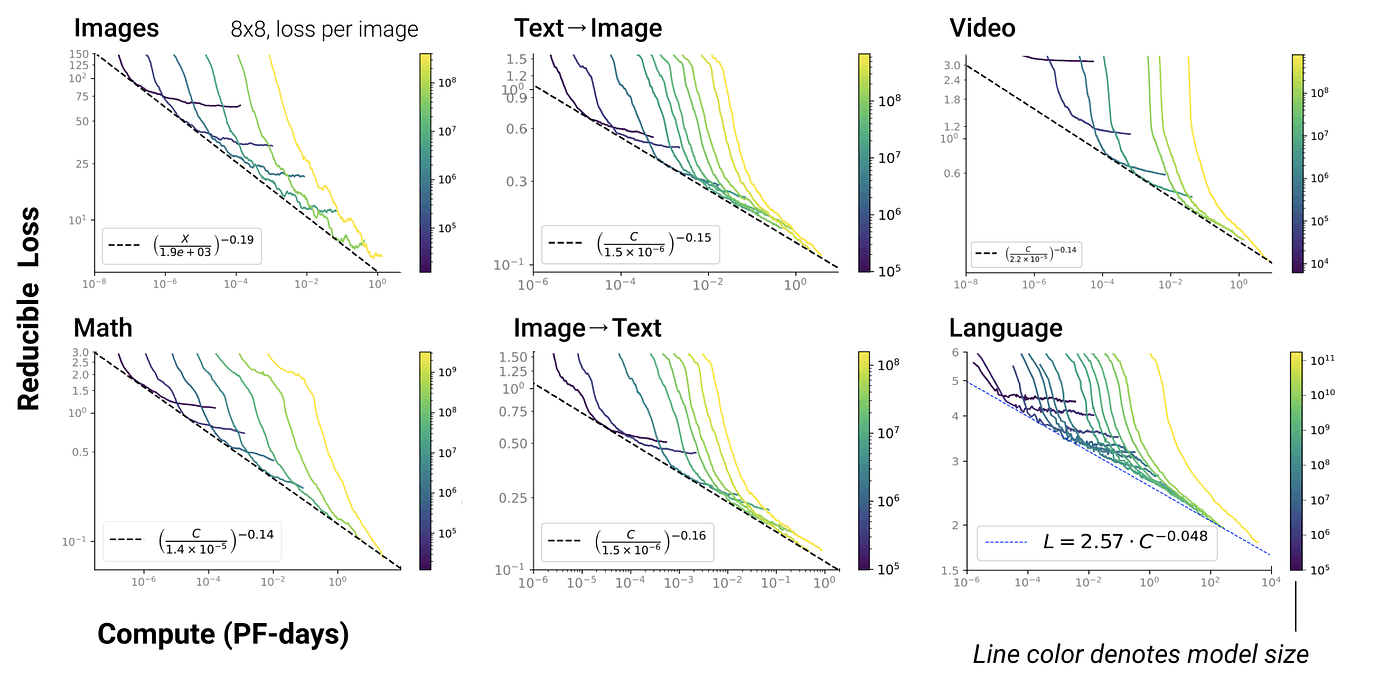
When researchers plot model cross-entropy loss against compute on a log-log scale, the result is a near-straight line: loss falls predictably as compute, model size, or training tokens increase. That empirical regularity - the scaling law - lets teams forecast returns, but it also shows the limit: buying more GPUs gives diminishing marginal returns.