Open model API pricing: pay per token, no subscription
, 3 min read, By Jaber Jaber
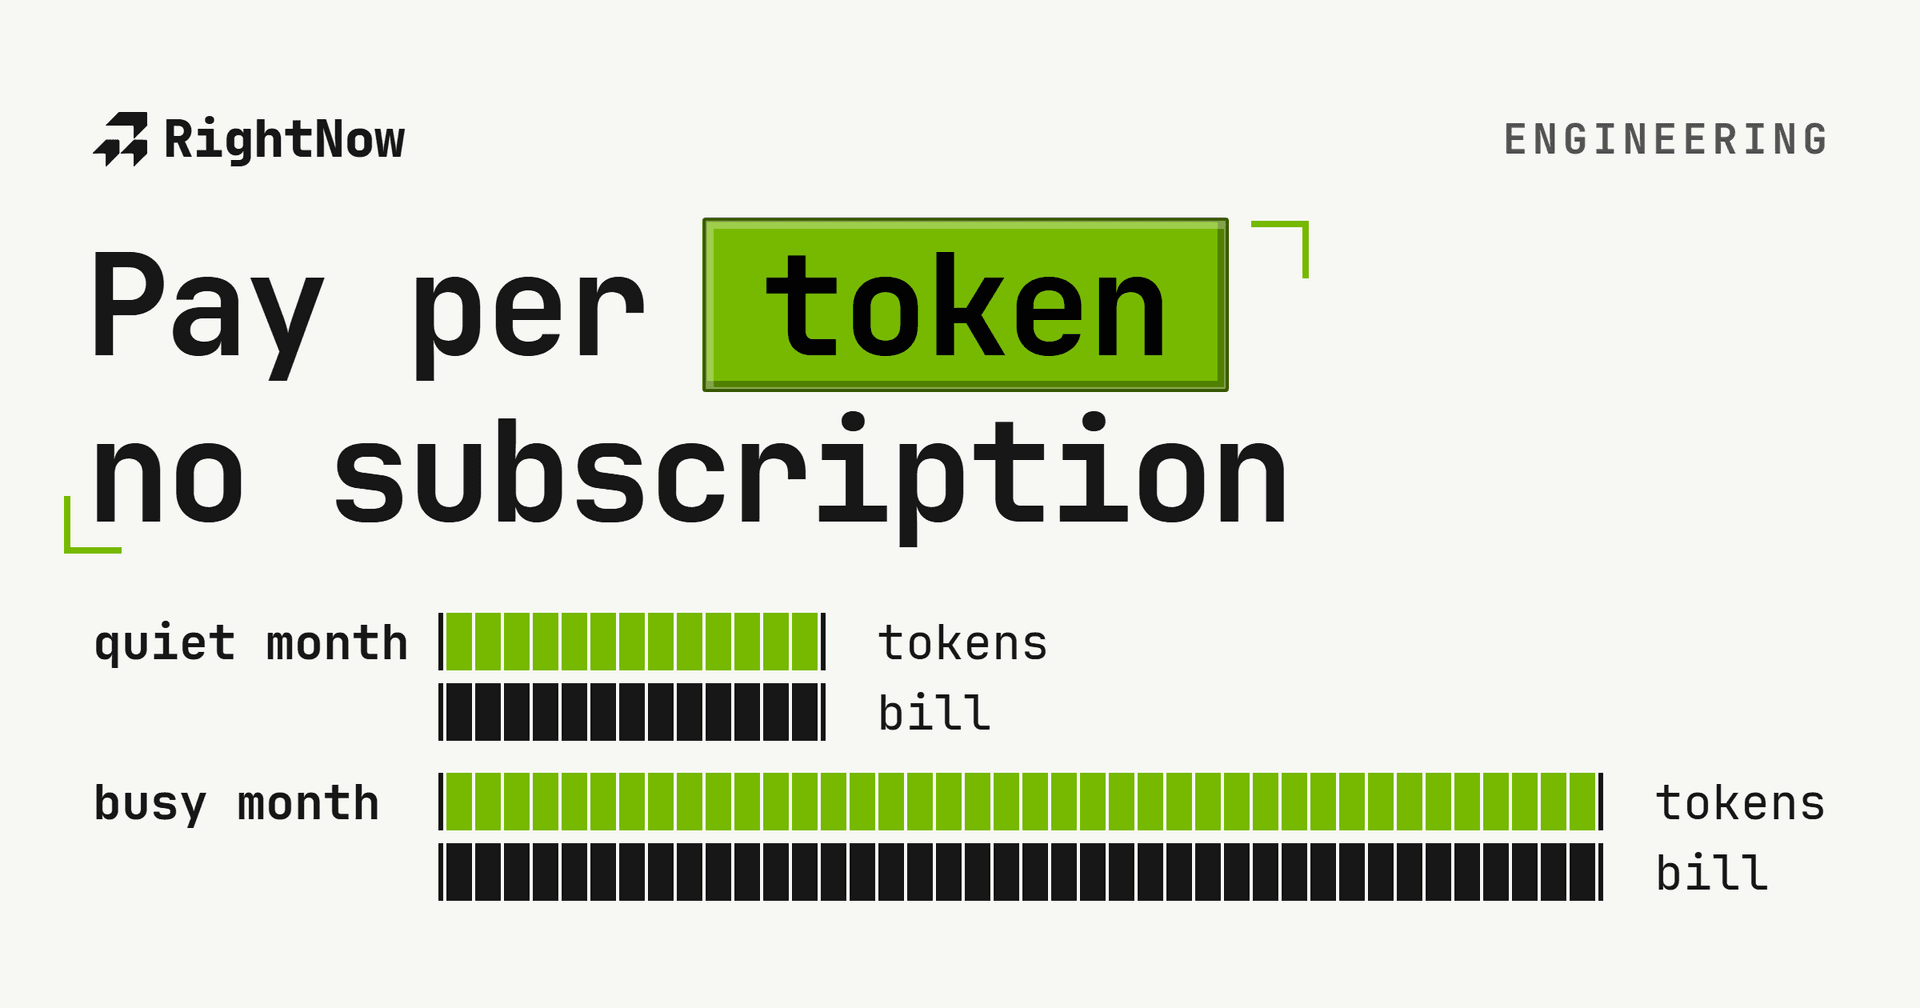
EngineeringThe RightNow open models API is pay per token, with no subscription and no per-seat fees. Each open-weight model has its own list price per million input and output tokens, and Batch runs a file of requests at half of list price. $1 free for a new account.
How is open model inference priced?
Priced per model. The Pricing page lists input, cached input and output rates per million tokens; without a separate cached rate, cached input bills at the input rate.
| Model | Input | Cached input | Output |
|---|---|---|---|
| Step 5 PreviewStepFun | USD 0.90 | USD 0.09 | USD 2.43 |
| DeepSeek V4.1 Flash 1017DeepSeek | USD 0.15 | USD 0.01 | USD 0.60 |
| GLM 5.3Z.ai | USD 1.30 | USD 0.13 | USD 4.20 |
| GLM 5.3 FlashZ.ai | USD 0.11 | USD 0.03 | USD 0.45 |

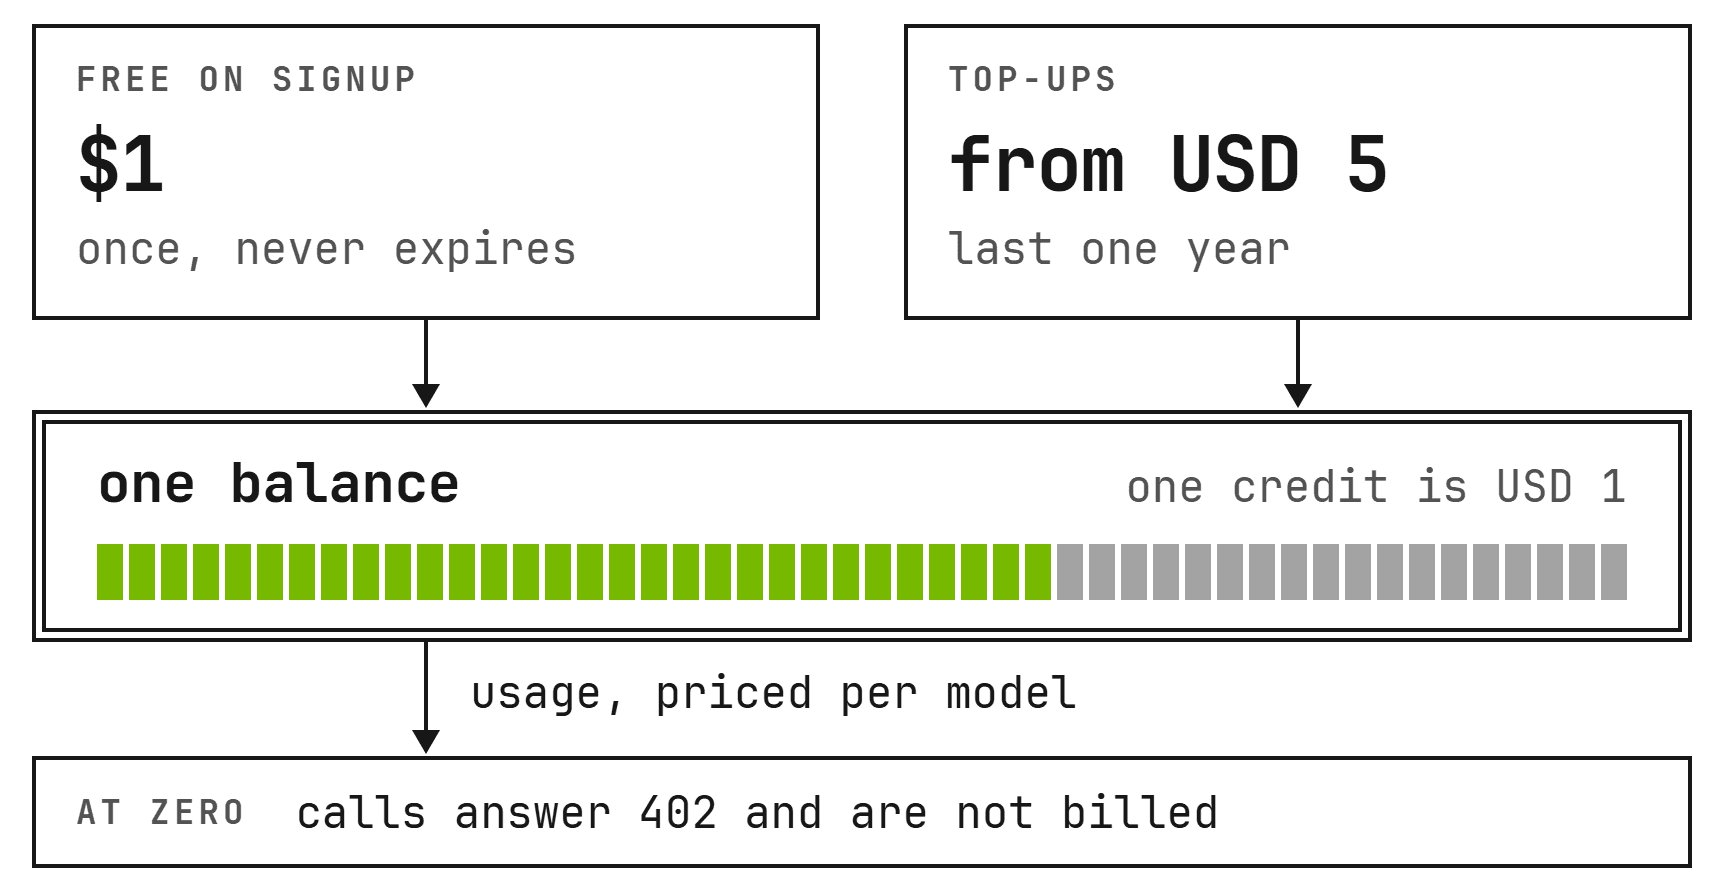
Each workspace has one balance. One credit is one US dollar. Add credits when you need them and pay as you go.
Is there a subscription or a seat fee?
No. Pay as you go is billed per token with no subscription, on shared capacity. There are no per-seat fees, and your price does not change with the size of your team.
No minimum spend: every account can call the open models API. Top-ups start at USD 5, with optional auto-recharge, and stay valid for one year. That $1 never expires.
What if our volume swings from month to month?
The bill counts tokens, so a quiet month costs less than a busy one. Set a monthly budget for each key. At zero balance, calls to the open models API return 402 Payment Required and are not billed.
Do limits grow as we scale?
Purchases raise your limits. Each key starts at 10,000 requests a minute, 50,000 once you buy credits, and 200,000 once your purchases reach USD 200. See Limits.
How do we lower a bill that keeps climbing?
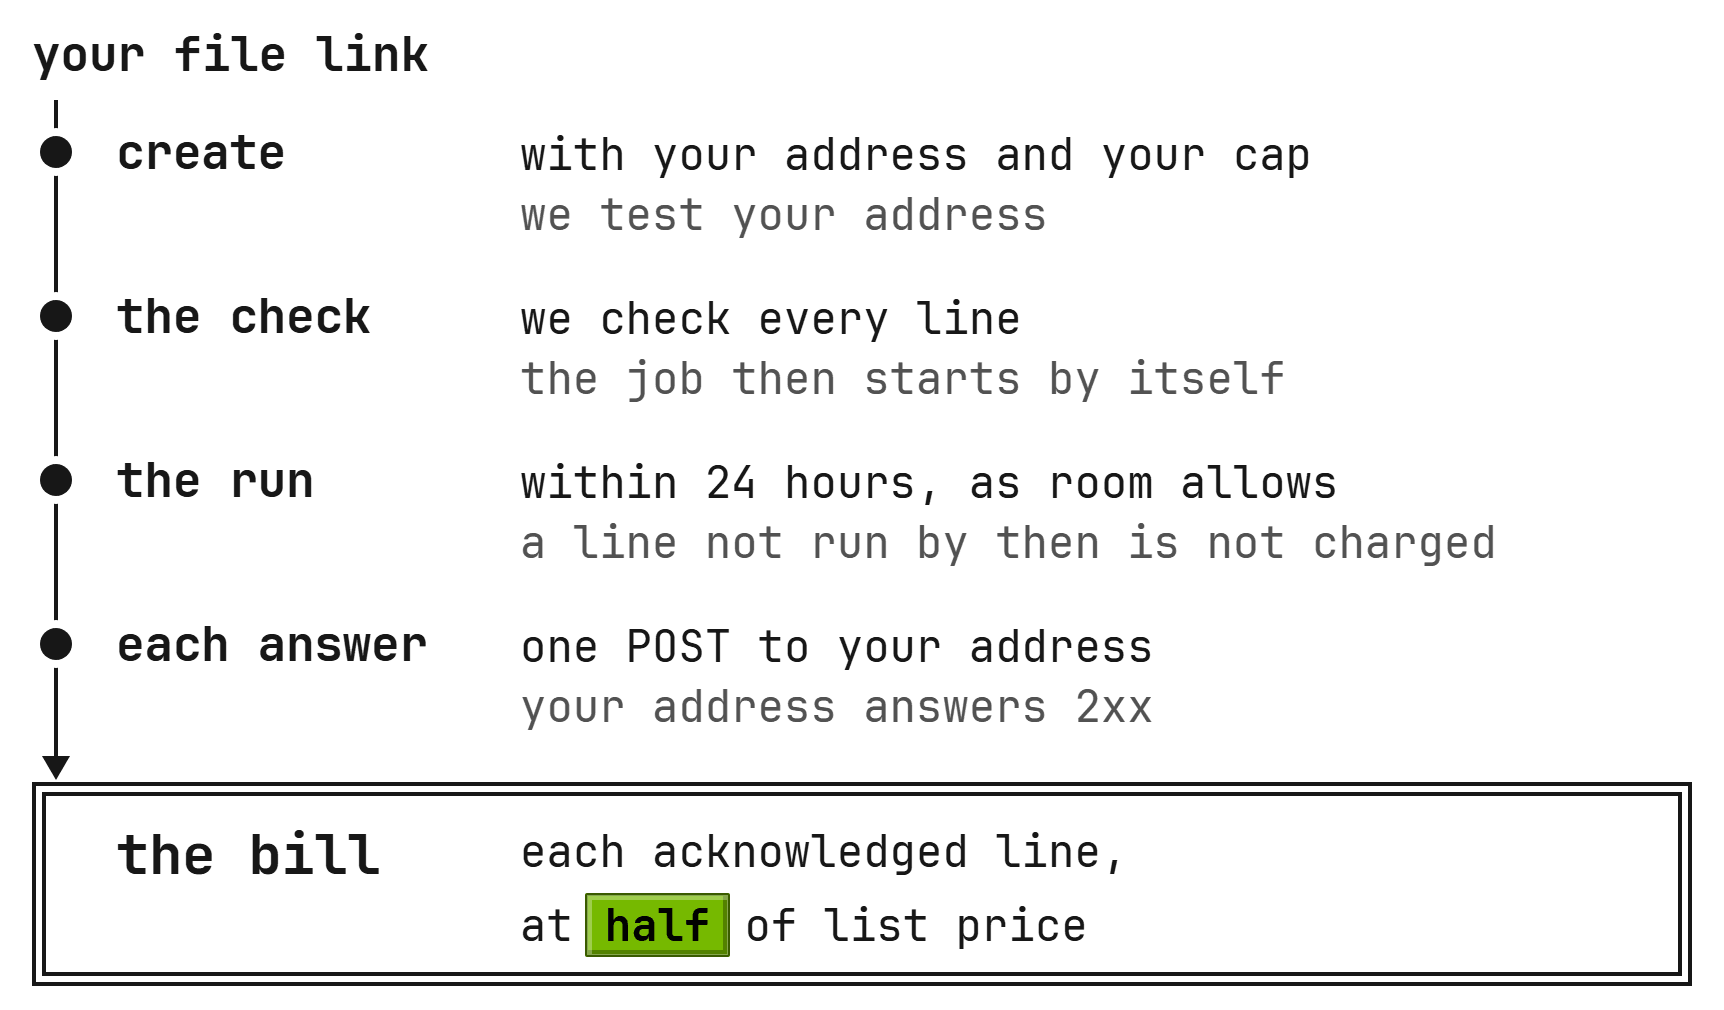
Batch runs a file of requests at half of list price, and each answer is posted to your own address. A job runs within 24 hours as room allows, and a line not run by then is not charged.
A line costs half of list price on input, cached input and output, and it is charged after your address answered 2xx. Batch uses a model's spare capacity, so there is no promised start time. If the work cannot wait, use the normal API.
One request can ask for the batch price too: send service_tier: "flex" with it. A request the batch price does not cover is not refused. It is served at the ordinary price.
Repeated prompts cost less: caching is automatic and best effort. Cached input is billed at the selected model's declared cached-input price. See Prompt caching.
What would a month cost?
Pick a model and type the tokens you expect in a month. The list amount is those input and output tokens at the model's list prices. The Batch amount is half of it, for a model that offers the batch price.
The amounts are worked out from list prices. Every model's prices are on the Pricing page.
How do we start?
$1 free for a new account. The quickstart, Call an open model, takes you from a workspace key to a server-side chat request. Every open model has its own page, with its prices, under Open models.